Cost-Effective Enterprise RAG Architecture: Grounding AI in Documents

Comprehensive architectural guide on information retrieval pipelines that ground language models without expensive custom training runs.

Samuel Koesnadi··5 min read
Cost-Effective Enterprise RAG Architecture: Grounding AI in Documents
The challenge of grounding internal business documents in large language models historically centered on two barriers: compute expense and strict context limits.

Fine-tuning foundation models cost thousands of dollars and frequently exacerbated hallucination risks.

The Decoupled Information Retrieval Paradigm

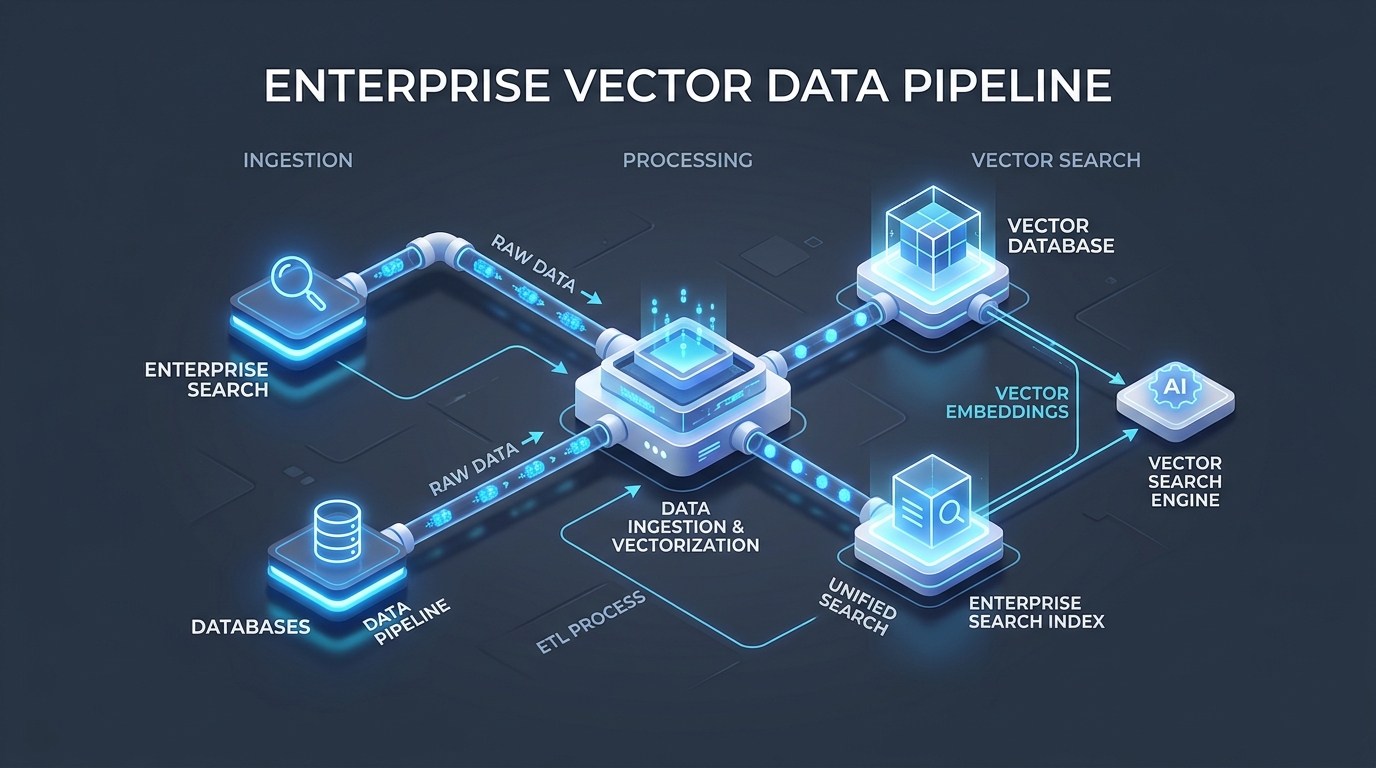
The elegant solution separates knowledge storage from generative synthesis:

  • Storage Layer: Enterprise documents are chunked and indexed into lightweight vector databases.
  • Semantic Retrieval: Upon receiving a query, mathematical embeddings isolate the top 3-5 relevant document fragments.
  • Context Synthesis: Retrieved fragments are injected directly into the prompt context as the strict source of truth for the model.
  • Core Advantages for Practical Deployment

    This architecture yields three decisive advantages: 1. Verifiable Accuracy: Responses are anchored exclusively in verified internal documentation. 2. Instant Updates: Adding new catalog items requires updating a text document, with zero retraining latency. 3. Minimal Hardware Overhead: Vector similarity checks execute in milliseconds on lightweight commodity VPS hardware.

    A thoughtfully architected lightweight pipeline consistently outperforms over-engineered custom fine-tuning systems.

    Bimbelai empowers individuals and businesses with practical, sovereign AI systems.

    Explore platform →
    More posts

    Ready to Put This Guide into Practice?

    Practice Live in Interactive Playgrounds

    Jump into our interactive browser playground and build alongside the Bimbelai community.